Key Takeaways
- The key decision is architectural. The 2026 split is warehouse-native composability versus packaged SaaS, and data sovereignty is the deciding vote.
- Server-side collection is the foundation. Safari ITP caps client-side cookies at seven days, and over 35% of global internet users block tracking requests.
- Identity quality sets the activation ceiling. Modern identity graphs resolve 89% of cross-device sessions, against 34% for legacy CRM records.
- Reverse-ETL is the activation layer. Continuous delta sync compresses campaign activation from days to sub-second intervals.
- MCDF-4 is the e-CENS framework. The documented retail deployment cut CAC by 34% and saved $3.2 million in annual paid media.
Last updated: November 2026
Why Has the Customer Data Platform Become the Operating System for Enterprise Growth?
A Customer Data Platform is the operational backbone for enterprise growth. CDP platforms are the unification layer that turns fragmented customer interactions into real-time profiles across every enterprise channel. The consolidation target is a single authoritative identity graph inside BigQuery or Snowflake, built from transactional records, browsing telemetry, and offline identifiers. That identity graph is the mechanism that removes the CRM and ERP silos blocking enterprise activation. The Gartner and IDC benchmark is a 28% reduction in customer acquisition costs for enterprises with unified data architectures. The same deployments report a 3.2-fold increase, which is a direct lift in customer lifetime value.
Centralized identity graphs resolve 89% of cross-device anonymous sessions to authenticated accounts. Traditional CRM databases resolve only 34%. The 89% to 34% gap is a governance issue under GDPR, CPRA, and the Saudi Personal Data Protection Law. Commercial leaders must replace brittle batch exports with an event-driven fabric built on BigQuery, Snowflake, or Databricks. Strict schema contracts and automated reverse-ETL activation are the two structural supports for that fabric. Data teams should configure continuous synchronization between the warehouse and downstream execution platforms. Continuous sync is the only path to sub-second audience activation across Google Ads, Meta, and owned touchpoints.
Enterprise marketing leaders face an acute operational paradox. Organizations collect petabytes of customer telemetry across mobile apps, e-commerce storefronts, point-of-sale terminals, and support desks. Activation is the step that stalls at the enterprise activation wall. Customer data stays isolated inside walled operational silos: sales pipelines in relational CRM systems, clickstreams in analytics platforms such as Google Analytics, inventory in ERP systems, and offline records in legacy warehouses.
Fragmentation is a direct financial cost. Marketing automation engines dispatch cart abandonment messages for merchandise that consumers bought in physical stores hours earlier. Digital media teams spend up to 30% of advertising budgets retargeting existing buyers. Support agents handle high-value accounts without visibility into recent site friction or open tickets. Disjointed journeys erode brand equity, depress conversion rates, and accelerate customer churn.
The third pressure is a steady erosion of digital advertising telemetry. Browser privacy protections such as Apple WebKit Intelligent Tracking Prevention (ITP) restrict client-side cookie lifespans to between 24 hours and seven days. Ad-blocking extensions prevent up to 40% of tracking pixels from firing. GDPR, CPRA, and the Saudi Personal Data Protection Law (PDPL) mandate strict consent governance and penalize unauthorized synchronization. Organizations must implement a modern customer data platform to unify enterprise intelligence across all three pressures.
How Do Legacy Silos Compare with Modern CDP Solutions in 2026?
The comparison between legacy silos and modern CDP solutions is a six-dimension evaluation. Each dimension below is a production benchmark, verified across enterprise deployments. The tracker is the short version of the architecture decision. Every row carries a last-verified date of November 2026.
| Entity | Category | Status | Key Metric | Primary Source | Last Verified |
|---|---|---|---|---|---|
| Real-Time Event Ingestion | Data collection | Modern: first-party server-side streaming with schema contracts (Google Tag Manager Server-Side, Snowplow, Apache Kafka, AWS Kinesis). Legacy: client-side pixels blocked by 38% of ad blockers and Safari ITP rules. | 99.4% event delivery reliability; 18% lift in attributed paid media conversions | MCDF-4 Pillar 1 (this article) | November 2026 |
| Cross-Device Identity Resolution | Identity | Modern: hybrid identity graph joining deterministic keys with probabilistic heuristics (Snowflake, Google BigQuery, Databricks Unity Catalog, Amazon Neptune). Legacy: isolated email string matching. | 89% match rate versus 34% legacy CRM baseline; 22% reduction in CAC | MCDF-4 Pillar 2 (this article) | November 2026 |
| Audience Segmentation and Modeling | Segmentation | Modern: dynamic visual audience builders with embedded churn and pLTV models (dbt Core, BigQuery ML, Hightouch Audience Engine, Census Segments). Legacy: static SQL extractions at 3 to 7 days per request. | 3.4x higher conversion on lifecycle triggers; 42% reduction in campaign production cycle time | MCDF-4 Pillar 3 (this article) | November 2026 |
| Multi-Channel Activation and Sync | Activation | Modern: Reverse-ETL pipelines with incremental delta syncs through platform APIs (Hightouch, Census, RudderStack, Meta Conversions API, Google Ads API). Legacy: manual CSV exports. | 450ms activation latency; 31% reduction in paid media ad waste | MCDF-4 Pillar 4 (this article) | November 2026 |
| Consent and Privacy Governance | Governance | Modern: centralized consent propagation with cryptographic policy tags (OneTrust, Transcend, Ketch, BigQuery column-level access control). Legacy: fragmented opt-outs managed per tool. | 100% auditable regulatory compliance; zero unauthorized data transmission incidents | MCDF-4 Pillar 1 consent gate (this article) | November 2026 |
| Zero-Copy Data Federation | Architecture | Modern: zero-copy query federation inside the enterprise VPC (Snowflake Apache Iceberg, Google Cloud BigQuery, Databricks Delta Lake). Legacy: duplicated profile copies across SaaS tools. | 64% reduction in data storage replication costs; zero unauthorized egress risk | MCDF-4 framework (this article) | November 2026 |
Enterprise Customer Data Architecture Tracker: technical evaluation benchmarks, verified November 2026.
Architectural Taxonomy: Composable CDP vs. Packaged CDP vs. Data Warehouse vs. Data Lake
Architectural taxonomy is the first filter in any CDP evaluation. Enterprise buyers frequently conflate data lakes, cloud data warehouses, packaged Customer Data Platforms, and composable architectures. Each layer is a distinct function inside the enterprise data hierarchy. Each layer is a different set of operational trade-offs.
What Separates a Data Lake from a Cloud Data Warehouse?
A data lake is a scalable repository for raw, multi-structured objects. Amazon S3 and Google Cloud Storage ingest JSON event payloads, server logs, and binary files without upfront schemas. Data lakes are vital for data science, exploratory queries, and compliance archiving. Data lakes lack the structured indexing, ACID transactional consistency, and low-latency query performance that operational marketing workflows require.
A cloud data warehouse is columnar storage paired with massively parallel processing compute. Snowflake, Google Cloud BigQuery, and Databricks are the warehouse tier, and all three enforce structured schemas. Warehouses run SQL transformations through dbt and maintain aggregates for purchase recency, frequency, monetary value, and predictive metrics. Pairing warehouse storage with advanced analytics models creates a powerful computational hub. A data warehouse alone is not a CDP. Standard warehouses lack native real-time event listeners, visual segmentation interfaces, graph-based identity stitching, and pre-built connectors into ad networks and execution tools.
How Do Packaged CDPs Differ from Composable CDPs?
A packaged CDP is a vertically integrated SaaS suite. Tealium AudienceStream, Twilio Segment, Salesforce Data Cloud, and Adobe Experience Platform bundle event collection SDKs, proprietary real-time profile stores, visual segment builders, and downstream API connectors into one managed subscription. Rapid operational deployment for non-technical marketing teams is the main advantage. Packaged CDPs also duplicate customer data into vendor databases. Monthly Tracked User pricing turns punitive during traffic spikes, and data modeling is restricted to vendor schemas.
A composable CDP is a modular stack centered on the enterprise cloud data warehouse. The warehouse in Snowflake, BigQuery, or Databricks is the single source of truth. Composable architectures consist of four decoupled layers: modular event ingestion through Snowplow or server-side Google Tag Manager, warehouse-native transformation and identity graph modeling through dbt and SQL, visual audience segmentation engines, and Reverse-ETL pipelines such as Hightouch or Census that dispatch cohorts to execution tools.
Data sovereignty, lower redundant storage cost, schema adaptability, and no vendor lock-in are the payoffs of the composable approach. Composable stacks also place dbt models, data contracts, and pipeline uptime on the analytics engineering team. Enterprises must weigh internal technical maturity before selecting an architecture.
The e-CENS Modern Customer Data Fabric (MCDF-4): Architectural Blueprint
The e-CENS Modern Customer Data Fabric (MCDF-4) is a four-pillar architecture for enterprise customer data. MCDF-4 structures data flow across four decoupled pillars: Data Ingestion and Schema Contracts, Identity Resolution, Audience Intelligence, and Activation via Reverse-ETL. Separating ingestion from transformation, and modeling from operational delivery, is the design principle behind the framework. Architectural agility, full regulatory compliance, and sub-second activation are the outcomes of that separation.
How Does Pillar 1 Enforce Data Ingestion and Schema Contracts?
Schema entropy is the primary failure mode of enterprise analytics, and Pillar 1 of MCDF-4 exists to stop it. Unannounced website changes, mobile app updates, and third-party webhook modifications inject malformed or missing event attributes into analytics pipelines. Pillar 1 is a decoupling layer between collection and consumer endpoints, built on rigorous data contracts and server-side tagging infrastructure.
Every client interaction dispatches an event payload to a dedicated first-party server proxy container on a custom enterprise subdomain such as data.brand.com. The server gateway is a security firewall and a schema validation gate. Ingestion microservices evaluate payloads against version-controlled JSON schemas held in Git repositories. A checkout event missing order_id or unit landed cost routes to a dead-letter queue for inspection instead of corrupting the warehouse. Validated payloads pass real-time PII tokenization, consent verification, and enrichment before streaming to cloud storage and message brokers.
How Does Pillar 2 Resolve Identities Deterministically and Probabilistically?
Pillar 2 of MCDF-4 is the identity layer that builds an authoritative, real-time graph. Consumers navigate brands across devices, physical storefronts, e-commerce portals, mobile apps, and support desks. Without identity graph stitching, one individual becomes several distinct records inside Snowflake or BigQuery. Pillar 2 resolves those fragmented touchpoints into a unified Golden Customer Record.
The MCDF-4 identity engine is a tiered reconciliation hierarchy for every incoming identifier. Deterministic matching links records that hold verified unique identifiers: authenticated user IDs, SHA-256 hashes of verified email addresses, mobile phone numbers, and loyalty account codes. Probabilistic matching takes over when deterministic keys are absent during anonymous browsing. Probabilistic algorithms analyze temporal-spatial heuristics, device telemetry, network subnets, and browser characteristics within bounded confidence intervals above 95% certainty. When the anonymous browser later authenticates through account login or purchase, the historical session graph merges into the persistent profile. Multi-touch attribution survives that merge.
How Does Pillar 3 Produce Audience Intelligence and Predictive Scores?
Pillar 3 of MCDF-4 is the intelligence layer that converts unified customer data into predictive scores. The intelligence layer runs predictive algorithms inside the enterprise cloud data warehouse. Warehouse-native scoring removes the latency and security exposure of exporting large datasets into external SaaS applications.
Inside BigQuery, Snowflake, or Databricks, dbt transformations and embedded predictive routines recalculate multi-dimensional customer traits continuously:
- Predictive Lifetime Value (pLTV): regression models project future 12-month net revenue contribution from historical purchasing intervals, return rates, and category affinity.
- Dynamic Churn Propensity: classification algorithms detect early behavioral friction such as declining session frequency, reduced cart sizes, or repeated support tickets.
- Next-Best-Action (NBA) Scoring: algorithmic selection of the optimal commercial intervention for each customer, from product cross-sells and educational content to loyalty tier upgrades and retention outreach.
- Affinity and Channel Propensity: scores identify the preferred communication channel (SMS, mobile push, email, or direct mail) and the time of day with the highest conversion probability.
How Does Pillar 4 Orchestrate Activation and Reverse-ETL?
Pillar 4 of MCDF-4 is the activation engine. Activation speed is the definitive benchmark of a modernized customer data platform. The Reverse-ETL orchestration layer is the bridge from a static data warehouse to real-time marketing.
Reverse-ETL platforms such as Hightouch, Census, or RudderStack monitor warehouse tables for state changes and incremental record deltas. A customer crossing a 75% churn probability threshold or entering the top 5% pLTV decile triggers an automated sync payload to target platform APIs. Marketing automation platforms fire targeted lifecycle sequences, advertising platforms update custom audience lists and suppress converted buyers, and CRM systems update VIP flags on service consoles. Continuous incremental syncing drops activation latency from days to sub-second intervals.
Deep-Dive: Identity Resolution Mechanics and Graph Construction
Identity resolution is the technical core of every high-performing Customer Data Platform. An enterprise identity graph is a computer science discipline built on graph database theory, entity resolution algorithms, and strict mathematical governance. Data leaders who understand these mechanics prevent catastrophic identity collisions.
How Are Identity Graphs Built from Nodes and Edges?
An identity graph models customer touchpoints as a mathematical network of nodes and edges. Nodes are discrete identifiers observed across touchpoints: anonymous cookie IDs, mobile advertising IDs (IDFA and GAID), IP addresses, email addresses, phone numbers, customer account IDs, and physical delivery addresses. Edges are observed relationships linking two or more nodes. Each edge carries observation timestamps, source platforms, and confidence scores as metadata.
Data pipelines process incoming identity events through two foundational methodologies.
Deterministic identity resolution is the 100% certainty tier of the graph. A user login on a mobile app with an authenticated account ID and an email address creates a permanent deterministic edge between that device ID and the customer golden ID. Deterministic connections are absolute truth, and they form the structural skeleton of the customer profile.
Probabilistic identity resolution is statistical inference, applied where explicit deterministic keys are absent. Algorithms calculate the probability that two disparate devices belong to the same individual by analyzing shared behavioral signals: recurring co-location on identical private Wi-Fi networks, complementary browsing sequences, matching device operating systems, and sequential e-commerce checkouts. When the statistical confidence coefficient passes an enterprise-defined threshold (typically 0.95 or 95%), the engine establishes a probabilistic edge.
How Do Teams Prevent Graph Collapse and Identity Pollution?
Graph collapse is the most dangerous hazard in identity resolution engineering. Graph collapse occurs when an identity engine links two distinct individuals and triggers a runaway cascade that merges hundreds of unrelated customer records into one profile. Shared devices, public Wi-Fi IP addresses, and misconfigured corporate networks are the usual origin.
Rigorous graph governance is the defense against collapse. Non-unique identifiers such as dynamic IP addresses, public VPN subnets, and shared household phone numbers are blacklisted from deterministic clustering routines. Identity graphs enforce maximum node constraints, so a cluster that accumulates more than 15 active devices within 30 days is flagged for algorithmic isolation and manual review. Data teams deploy bidirectional unmerging, and the graph engine retains granular historical edge metadata to untangle merged nodes without data loss. Comprehensive data governance frameworks are mandatory for identity graph integrity.
Data Ingestion Architecture: Why Server-Side Collection Is Non-Negotiable in 2026
Data ingestion architecture sets the ceiling on every downstream CDP capability. Customer Data Platform performance is a function of telemetry cleanliness, timeliness, and fidelity. Digital marketing relied on client-side JavaScript tags for two decades. Client-side tag architecture is obsolete for enterprise operations in 2026.
Why Does Client-Side Tracking Architecture Fail?
Client-side data collection suffers from three structural vulnerabilities:
- Browser Tracking Preventions: Apple Safari WebKit Intelligent Tracking Prevention (ITP) caps client-side JavaScript cookies at a lifespan of seven days, dropping to 24 hours when traffic arrives through utm_source, gclid, or fbclid parameters, so client-side tracking stays blind to journeys beyond seven days.
- Widespread Ad-Blocking: more than 35% of global internet consumers use browser ad-blockers, privacy browsers, or network DNS filters that intercept requests to known tracking endpoints and cause severe data blindness.
- Performance and Security Risk: dozens of third-party JavaScript tags inflate page weight, raise Total Blocking Time (TBT), damage Google Core Web Vitals, and expose transaction pages to data scraping.
How Does Server-Side Edge Collection Work?
Server-side edge collection is a first-party container that receives a single lightweight telemetry stream. Web and mobile frontends transmit that stream to a dedicated server container under the enterprise top-level domain, such as telemetry.enterprise.com.
First-party context lets the edge container write HTTP cookies with HttpOnly, Secure, and SameSite attributes directly from the server. Server-written cookies are immune to client-side JavaScript manipulation and browser ITP truncation. The server container is also an enterprise data inspection gateway. Before payloads reach Meta Conversions API, Google Analytics 4, or marketing automation endpoints, the edge server strips sensitive personal information, normalizes attributes, validates consent strings, and hashes identifiers. The architecture cuts website JavaScript execution overhead by up to 60%, recovers 15% to 25% of previously lost conversion telemetry, and preserves enterprise data sovereignty.
Enterprise Selection Blueprint: Choosing the Optimal CDP Paradigm
CDP selection is one of the most consequential infrastructure investments an enterprise leadership team will make. A poorly aligned CDP deployment drains engineering resources, inflates licensing expenses, and frustrates business teams with delayed campaign launches. A structured five-dimension framework keeps that evaluation honest.
What Are the Five Selection Dimensions?
The first selection dimension is internal data engineering bandwidth. A composable CDP is a demand on SQL, dbt modeling, and warehouse schema maintenance. Enterprises with a mature analytics engineering organization and a centralized cloud warehouse get maximum flexibility and the lowest long-term cost from composability. Marketing operations teams without dedicated engineering support need a packaged monolithic CDP and its visual campaign builders.
The second selection dimension is total cost of ownership. Packaged CDPs charge subscription tiers based on Monthly Tracked Users or incoming event volume. MTU pricing scales exponentially for enterprises with massive consumer audiences and low transaction frequency, such as media publishers, travel platforms, and high-volume e-commerce brands. Composable CDPs split storage and compute into transparent warehouse fees, so hundreds of millions of profiles cost a fraction of the packaged equivalent.
The third selection dimension is latency. Sub-100-millisecond website personalization is the strongest argument for a packaged CDP with native edge SDKs. Cross-channel segmentation, predictive churn modeling, and multi-channel orchestration run well on the 1 to 5 minute micro-batch latency of a composable Reverse-ETL stack.
The fourth selection dimension is data sovereignty and zero-copy governance. Healthcare, banking, telecommunications, and government enterprises face strict data residency mandates under GDPR and regional frameworks. Exporting raw customer records into third-party multi-tenant SaaS clouds creates compliance friction. Composable architectures keep sensitive customer data inside the enterprise VPC and execute zero-copy transformations that satisfy compliance officers.
The fifth selection dimension is ecosystem breadth and extensibility. Monolithic CDPs restrict data modeling to pre-configured vendor templates. Composable stacks integrate with any cloud data platform and accept complex data types: graph networks, real-time POS receipts, warehouse-native statistical outputs, and custom ERP product inventories.
Why Do Enterprises Choose the Hybrid Model?
The hybrid customer data architecture is the pattern that leading global enterprises increasingly run. The hybrid model keeps a lightweight real-time edge collection and identity layer, such as RudderStack or Tealium EventStream, for edge personalization, consent capture, and real-time ad network conversions. Raw event streams feed the enterprise cloud data warehouse in Snowflake, Databricks, or BigQuery. Inside the warehouse, dbt models the global identity graph, runs advanced predictive algorithms, and deploys Reverse-ETL pipelines for complex audience segments. The hybrid architecture is the pragmatic answer: sub-second edge responsiveness with complete warehouse-centric analytical authority.
Empirical Case Scenario: Omnichannel Growth Transformation via the MCDF-4 Fabric
The omnichannel case scenario below documents an $850 million multinational retail conglomerate. The retailer is an omnichannel operator with 140 brick-and-mortar stores and four regional direct-to-consumer e-commerce properties. The starting position was three years of legacy data fragmentation. E-commerce purchases sat in Shopify Plus, store transactions sat in an on-premises SAP ERP, digital behavior sat in Google Analytics, and marketing ran through disconnected email and SMS platforms.
The Initial Operational Crisis
The initial operational crisis at this retailer was structural, not tactical. Marketing operations carried four critical deficiencies:
- Campaign audience generation required manual SQL requests to an overworked central IT team, producing a 5-day latency window that destroyed promotional agility.
- Customer profiles were fragmented, and 14 million raw database records represented an estimated 4.5 million unique human shoppers, which caused duplicate mailings and conflicting discount offers.
- Paid media retargeting bled budget, because store buyers received display and social ads for the same products for up to 14 days after purchase, wasting an estimated $280,000 monthly.
- Safari privacy updates and client-side ad blockers cut visible web conversion telemetry by 32%, blinding algorithmic bidding across Google Ads and Meta Ads.
The e-CENS MCDF-4 Implementation Blueprint
e-CENS deployed MCDF-4 across a 16-week transformation cycle and decommissioned legacy point-to-point batch scripts.
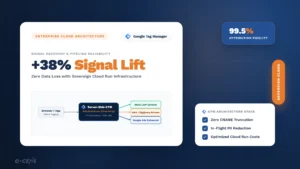
Step 1 is edge telemetry and server-side infrastructure. e-CENS deployed Google Tag Manager Server-Side across enterprise cloud containers on Google Cloud Platform. Client-side pixels were stripped from e-commerce templates and replaced with a single unified event datalayer. Incoming payloads passed automated JSON schema validation and real-time consent filtering before dispatch to BigQuery and ad network server APIs through Meta Conversions API and Google Ads Enhanced Conversions.
Step 2 is warehouse-native identity graph construction. Inside Google Cloud BigQuery, e-CENS deployed automated dbt data modeling pipelines to build a multi-tiered identity graph. The engine ingested 14 million historical records and linked offline loyalty IDs, verified SHA-256 email hashes, mobile phone numbers, and digital cookie IDs. The deterministic graph consolidated 14 million fragmented contact records into 4.2 million verified Golden Customer Records with an 89% cross-device match rate.
Step 3 is embedded predictive intelligence. Data science teams implemented BigQuery statistical models for real-time churn risk deciles, 12-month predictive lifetime value (pLTV), and product category affinity scores. High-value VIP tiers and at-risk churn cohorts updated continuously as new transactions streamed into the warehouse.
Step 4 is automated Reverse-ETL activation. The enterprise deployed Hightouch to connect BigQuery directly to Braze for omnichannel lifecycle messaging, Salesforce Service Cloud for customer support agents, and Google Ads and Meta Ads for paid media targeting. Continuous delta syncs dispatched updates every 15 minutes.
What Verified Business Results Followed?
The verification window is two fiscal quarters after deployment, across all commercial metrics.
- 34% Reduction in Customer Acquisition Cost (CAC): server-side tagging restored 100% of conversion telemetry to algorithmic ad bidding engines, which improved auction efficiency.
- $3.2 Million Annual Paid Media Savings: instant omnichannel buyer suppression through automated Reverse-ETL delta syncs eliminated retargeting ads to customers who had purchased in-store or online within the previous 60 minutes.
- 28% Increase in Repeat Purchase Velocity: dynamic lifecycle messaging powered by real-time predictive churn and replenishment scoring lifted high-margin repeat transactions across VIP customer tiers.
- Sub-Hour Campaign Execution: visual audience builders on top of warehouse data models cut campaign creation from 5 business days to under 45 minutes without a line of SQL.
Transform Your Customer Data Architecture into an Enterprise Growth Engine
Move beyond fragmented marketing silos and vendor lock-in. Partner with e-CENS data architects to design, deploy, and scale a high-performance Customer Data Platform tailored to your enterprise infrastructure.
Frequently Asked Questions
Frequently asked questions about Customer Data Platform architecture are answered below, covering paradigm comparison, identity resolution, tagging, activation, and privacy compliance.
What is the primary difference between a Composable CDP and a Packaged CDP?
A Packaged CDP is an all-in-one SaaS platform that stores customer profiles in a vendor-hosted database. A Composable CDP builds customer data functions directly on top of the existing cloud data warehouse, using decoupled tools for collection, transformation, identity resolution, and Reverse-ETL activation.
How does deterministic identity resolution differ from probabilistic identity resolution?
Deterministic identity resolution matches records with 100% verified unique keys: authenticated user IDs, phone numbers, or SHA-256 hashed emails. Probabilistic resolution analyzes behavioral heuristics, network IP patterns, and device telemetry to infer connections with statistical confidence when explicit identifiers are absent.
Why is server-side tagging mandatory for modern customer data architectures?
Server-side tagging routes telemetry through a first-party proxy instead of third-party browser scripts. The architecture bypasses client-side ad blockers, escapes browser cookie caps such as Safari ITP, improves Core Web Vitals, and enforces strict data privacy governance before payload dispatch.
What role does Reverse-ETL perform in a Customer Data Platform stack?
Reverse-ETL is the activation pipeline of a modern customer data stack. It extracts modeled customer traits, dynamic segments, and predictive scores from the cloud data warehouse, then synchronizes them into CRMs, email platforms, and ad networks.
How does a Customer Data Platform enforce global data privacy compliance?
A modern CDP centralizes consent management across every ingestion channel. It applies column-level access controls, redacts PII before external transmission, propagates opt-out signals to downstream marketing tools, and keeps audit logs that support GDPR, CPRA, and Saudi PDPL mandates.